Review
What Is AtlasFold? Protein Structure Prediction in Metagenomic Data
 Yasin Polat
 the Omics · Review

Through metagenomic studies, we can obtain millions of DNA sequences from soil, seawater, the gut microbiome, and various environmental samples. When these sequences are translated into proteins, we encounter an enormous protein universe. However, there is an important problem here. Having a protein sequence does not mean that we know what that protein does.
Especially in metagenomic data, sufficiently close homologs cannot be found in existing databases for many proteins. As a result, it can be difficult to predict the function of these proteins based solely on sequence similarity. The newly announced AtlasFold presents an interesting approach to this problem. It aims to extract information about a protein's three-dimensional structure directly from its sequence.
From Protein Sequence to Structure
One important way to understand the biological properties of a protein is to know its three-dimensional structure. This is because the amino acid sequence largely determines how a protein folds and how different regions of the chain are positioned in three-dimensional space. The resulting three-dimensional structure can provide important clues about which molecules the protein may interact with and which biological functions it may perform.
Experimentally determining protein structures is not always easy. Although methods such as X-ray crystallography, NMR, and cryo-EM provide highly valuable structural information, they cannot always be applied rapidly and at large scale to every protein. For this reason, artificial intelligence-based protein structure prediction systems such as AlphaFold have made major advances in predicting three-dimensional structures from protein sequences in recent years.
However, the information used in protein structure prediction is not limited to the amino acid sequence itself. In particular, many approaches use methods such as multiple sequence alignment (MSA) to take advantage of the evolutionary context of a protein. The reason is relatively simple. When we compare homologs of the same protein from different organisms, we can obtain important information about which regions of the structure have been conserved throughout evolution and which regions have co-evolved.
The problem is that we cannot find enough homologs for every protein.
This is particularly evident in metagenomic data. A newly discovered protein may have a very distant evolutionary history, or sufficiently similar sequences may not be available in existing databases. In such cases, constructing an MSA becomes more difficult, while the evolutionary information available for structure prediction may also become limited.
AtlasFold's approach differs precisely at this point. During structure prediction, the model aims to extract structural information directly from the protein sequence by leveraging patterns learned from large-scale protein sequences, without requiring an MSA.
Why Is MSA Important?
MSA, or multiple sequence alignment, is a method that allows us to compare similar protein sequences and identify conserved and variable regions among them. For example, when we align versions of the same protein from different organisms, we may observe that some amino acids have been conserved for millions of years. We may also notice that certain positions have changed together across different species.
These observations can provide important clues about protein structure. For example, if amino acids in two different regions of a protein have co-evolved over time, those regions may have a structural relationship in three-dimensional space.
However, this approach has an important prerequisite. We first need to find a sufficient number of similar proteins that we can compare.
This is not always possible in metagenomic data. Close homologs of a newly discovered protein may not be present in existing databases. In such a case, constructing an MSA becomes difficult, and the evolutionary information available for structure prediction is reduced.
This is where one of AtlasFold's important features emerges. The model aims to extract structural information directly from the protein sequence during structure prediction without requiring an MSA.
How Does AtlasFold Work?
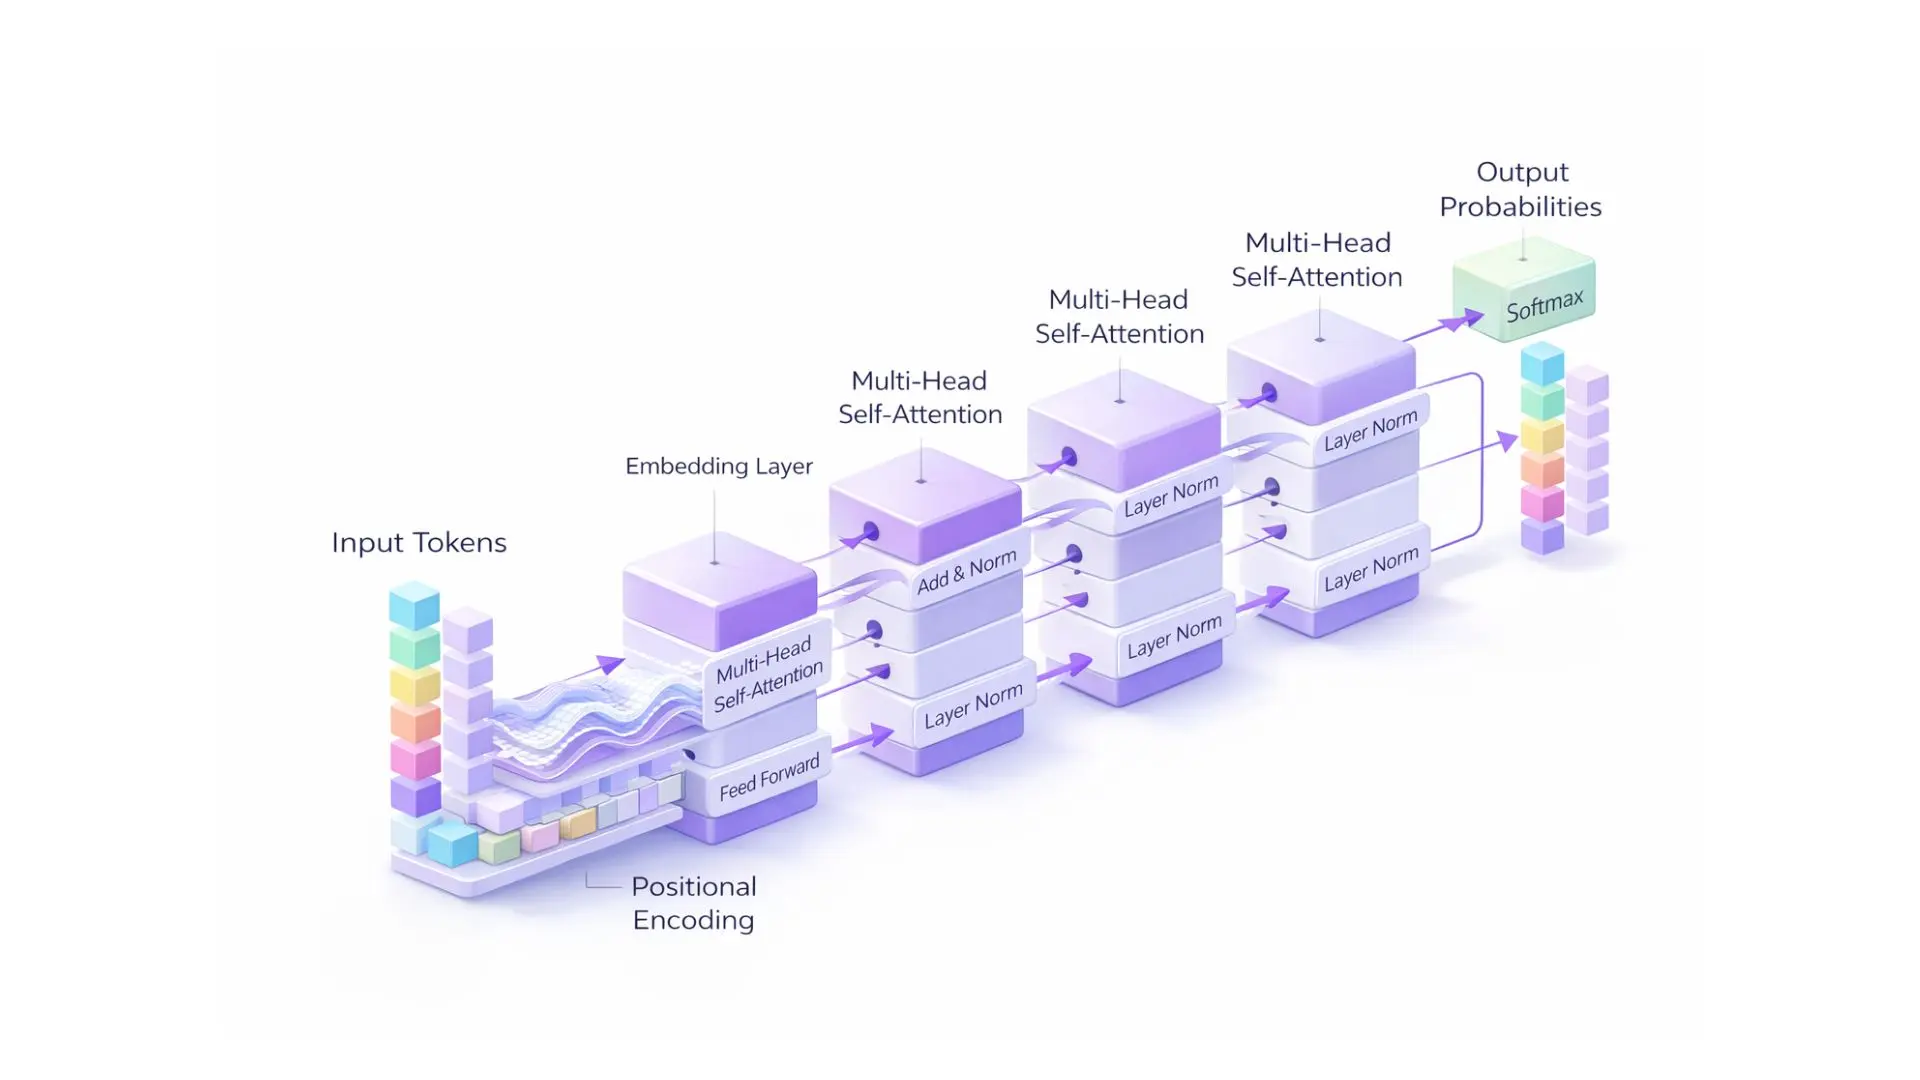
One of the core components behind AtlasFold is a protein language model called AtlasLM-3B. This model was trained on approximately 1.56 billion protein sequences.
To understand the concept of a "protein language model," it is useful to draw an analogy with natural language models. Large language models learn how words occur in different contexts and learn complex relationships within language from enormous amounts of text. In protein language models, amino acids take the place of words, while protein sequences take the place of sentences.
As the model encounters billions of protein sequences, it can learn various patterns concerning the relationships between amino acids. For example, tendencies for certain amino acids to occur at particular positions, or relationships between distant regions of a sequence, may contain structural information about how a protein can fold.
AtlasFold uses these learned patterns to generate predictions about three-dimensional structure directly from the protein sequence. An important difference here is that, when predicting the structure of a particular protein, it does not necessarily have to first identify a large number of homologous proteins and construct an MSA from them.
This approach is particularly interesting for proteins that are evolutionarily distant or have not been well characterized previously. The model does not necessarily require access to a large collection of homologous sequences for every new protein.
What Does AtlasFold's Performance Tell Us?
AtlasFold's performance has been evaluated using different protein structure prediction benchmarks, including CAMEO22, CASP14, and CASP15. These benchmarks enable structure prediction methods to be compared with experimentally determined structures and allow their performance to be evaluated on targets whose structures were previously unknown.
The reported results for AtlasFold include an average TM-score of 0.865 on CAMEO22, 0.732 on CASP14, and 0.701 on CASP15.
So, What Do These Numbers Mean?
The TM-score is one of the metrics used to evaluate the overall structural similarity between a predicted protein structure and its experimentally determined reference structure. As the score approaches 1, the two structures are considered to be more structurally similar.
Therefore, the reported average TM-score of 0.865 on CAMEO22 indicates that AtlasFold generated predictions showing a high degree of structural similarity to the experimentally determined structures of the proteins evaluated in that benchmark. However, 0.865 should not be interpreted as "86.5% of the structure is correct." TM-score is not a percentage of accuracy; rather, it is a score that evaluates the overall similarity between two three-dimensional structures.
The fact that the scores on CASP14 and CASP15 are 0.732 and 0.701, respectively, also indicates that performance can decrease on more challenging structure prediction problems. However, it is important to remember that these benchmarks do not consist of exactly the same targets and that their evaluation conditions are not identical. Therefore, rather than simply comparing the scores with one another, it is more appropriate to recognize that AtlasFold can capture meaningful structural similarity across different evaluation settings.
In other words, these results indicate that an MSA-free approach can capture structural signals that are useful for protein structure prediction. However, they do not support the conclusion that the model performs at the same level for every protein.
Why Is This Important for Metagenomics?
This is where AtlasFold becomes particularly interesting.
In metagenomic analyses, we can obtain hundreds of thousands or even millions of protein sequences. While some of these proteins can be readily associated with protein families in existing databases, finding close homologs can be difficult for a substantial proportion of them. Consequently, functional annotation based solely on sequence similarity may be insufficient to characterize the entire metagenomic protein universe.
Predicting protein structure can provide a different analytical layer. For example, AtlasFold could generate a structural prediction for a previously uncharacterized protein sequence. Researchers could then compare this prediction against known protein structures to investigate whether the protein resembles a particular protein family or functional class.
This approach can broadly be thought of as "sequence → structure → function." First, we have an amino acid sequence. If we cannot reliably infer its function directly from the sequence, an artificial intelligence model can be used to predict a possible three-dimensional structure. This structure can then be compared with the structures of known proteins to develop new hypotheses about its function.
An important point here is that structure prediction alone does not definitively determine a protein's function. Structural similarity can provide a strong clue, but reaching a functional conclusion may require the combined evaluation of sequence characteristics, structural similarities, phylogenetic information, and experimental validation.
Is AtlasFold Replacing AlphaFold3?
Does this mean that AtlasFold can replace AlphaFold3? It is too early to make such a claim. In fact, the two models do not address exactly the same problem. Therefore, this may not be the most appropriate question to ask in the first place.
AlphaFold3 is a broader system that addresses proteins as well as DNA, RNA, ligands, and different types of biomolecular interactions. The strength of AtlasFold lies in a different area. It attempts to predict protein structure directly from the protein sequence without using an MSA, leveraging information learned by a large protein language model.
This could be particularly interesting for metagenomic data. We have millions of protein sequences, and for a substantial proportion of them it can be difficult to find a sufficient number of homologs. In such cases, being able to predict structure without requiring an MSA may represent a genuinely useful approach.
Why Does Open Source Matter?
Another notable feature of AtlasFold, in addition to its performance, is that the project has been released as open source. The availability of the code, model weights, and related components allows researchers to examine the system within their own infrastructure and test it on different datasets.
This may be particularly important for metagenomic research. Metagenomic datasets are continuously expanding, and analyzing millions of protein sequences creates substantial computational requirements. The ability to run the model on researchers' own infrastructure may make it easier to integrate AtlasFold into large-scale protein structure prediction workflows in the future.
There are still millions of proteins in the metagenomic world whose functions, folding mechanisms, and roles in biological processes remain unknown. The patterns learned by large protein language models from billions of sequences may help us investigate these unknown proteins not only at the sequence level but also at the structural level.
From this perspective, AtlasFold is one of the notable approaches that adds the question "What kind of structure might this protein have?" alongside "What does this protein look like?" in metagenomic analysis.
Future studies involving larger datasets, more challenging benchmarks, and real metagenomic samples will provide a clearer picture of how far this approach can go in practice. For a significant proportion of the proteins in metagenomes that we currently label as having an "unknown function," the answer may lie not only in their sequences but also in their three-dimensional structures.
Subscribe to the newsletter
Get updates straight from me — no spam.